Open to Work / DATA ENGINEER & BUILDER
I’m Namazbek. I turn complex data into
reliable systems — and good ideas into things that work.
- Python✳
- SQL✳
- Apache Airflow✳
- dbt✳
- Apache Iceberg✳
- Trino✳
- Docker
01 / EXPLORE
Selected work
untverse
Gamified UNT Informatics learning platform built with Next.js, FastAPI and PostgreSQL.
I treat data systems like banking systems: correctness first, fast second. That mindset turns pipelines into durable products — observable, testable, and trusted.
03 / EXPLORE
Notes from the field
Practical Query Optimization in Postgres: Indexes, Partitioning, and Plan Introspection
Learn how to speed up Postgres queries with B-tree indexes, table partitioning, and EXPLAIN ANALYZE. Step-by-step with real Python code.
Designing ETL for AI: Building Robust Feature Pipelines and Feature Stores
Learn how to build reliable ML feature pipelines in Python: ingestion, transformation, storage, and serving — with Docker and pytest.
Python Performance for Data Pipelines: Profiling, Vectorization, and Safe Concurrency
Profile Python pipelines, replace slow loops with NumPy vectorization, and safely parallelize I/O with ThreadPoolExecutor. Step-by-step with Docker.
04 / PLAY & EXPERIMENT
A small lab.
A lot of curiosity.
Useful little tools for the everyday work of building things. Try an idea, follow a signal, connect the dots.
Enter the lab05 / THE BOOKSHELF
Ideas worth
keeping close.
Systems thinking, software craftsmanship, and the books that help me see the work a little differently.
Browse my libraryPersonal archive
More than the work.
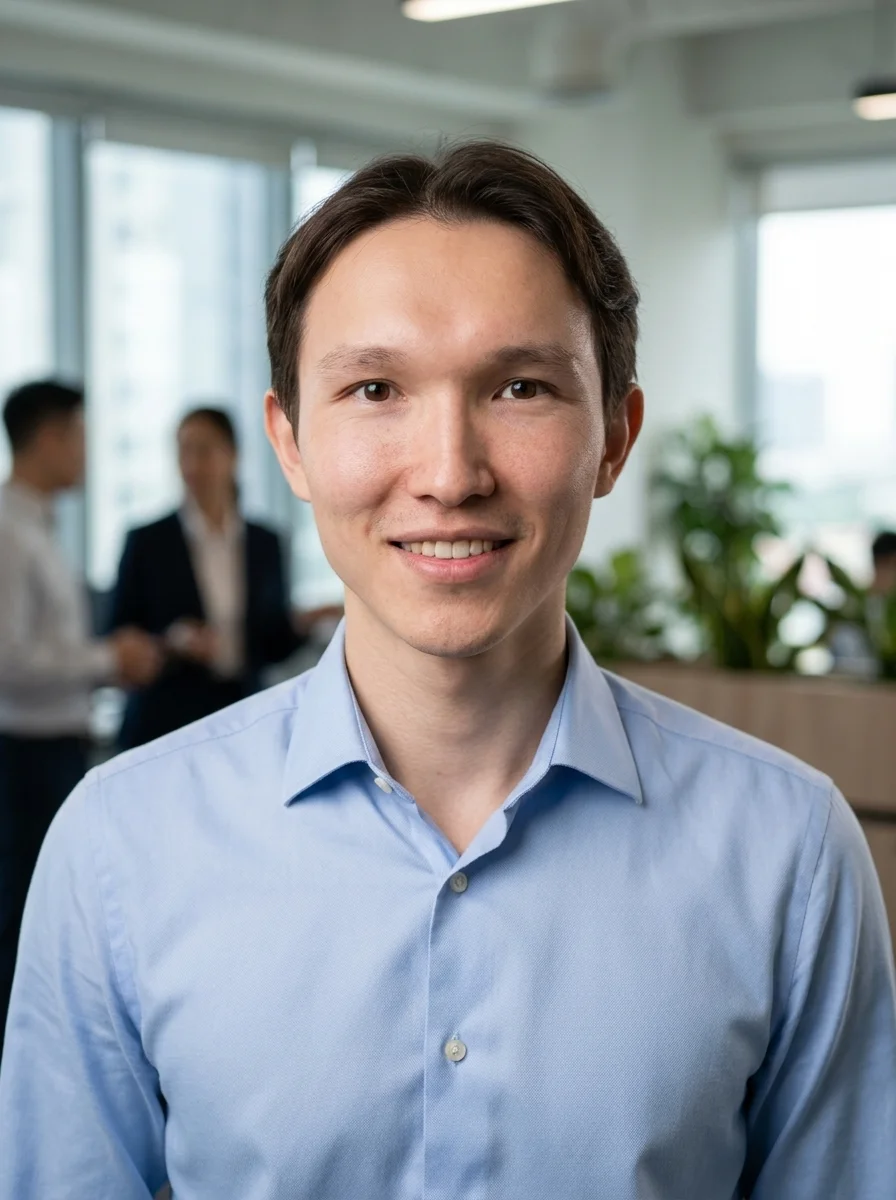
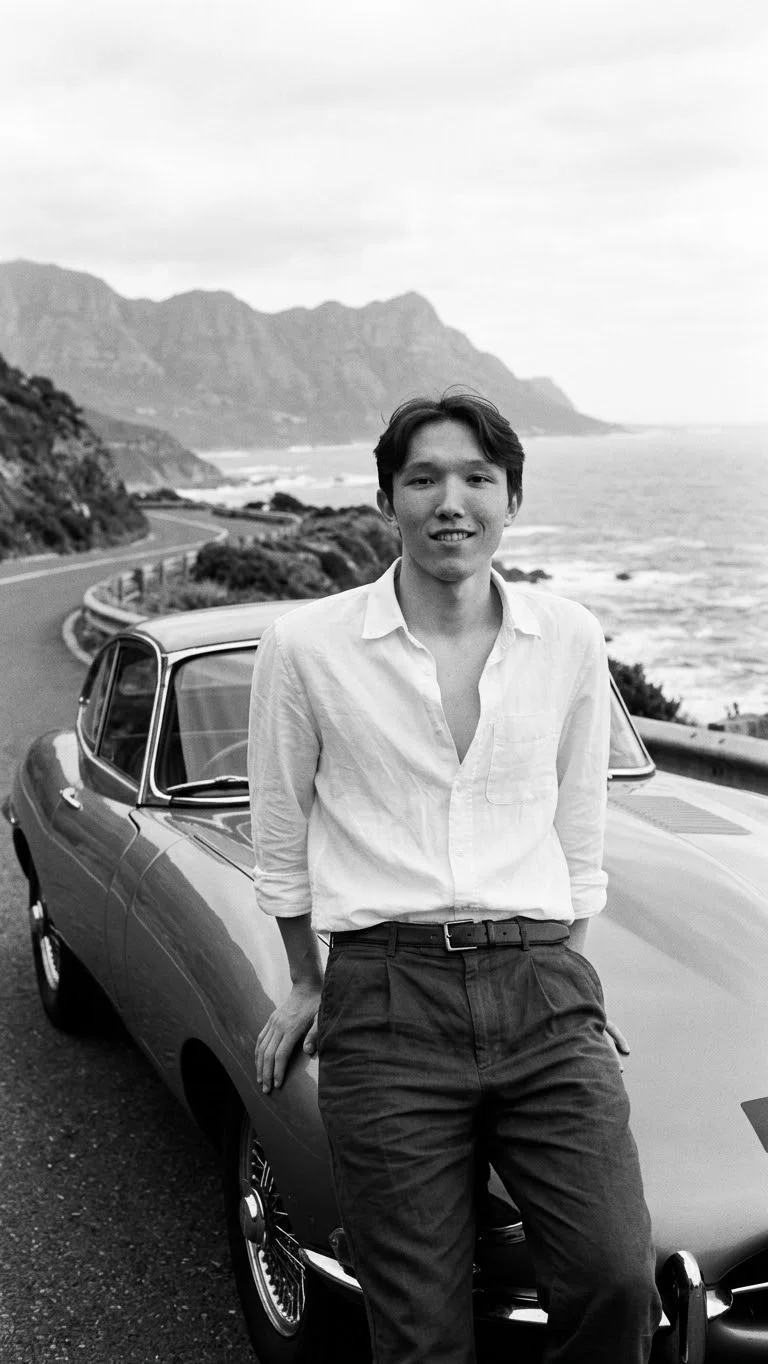
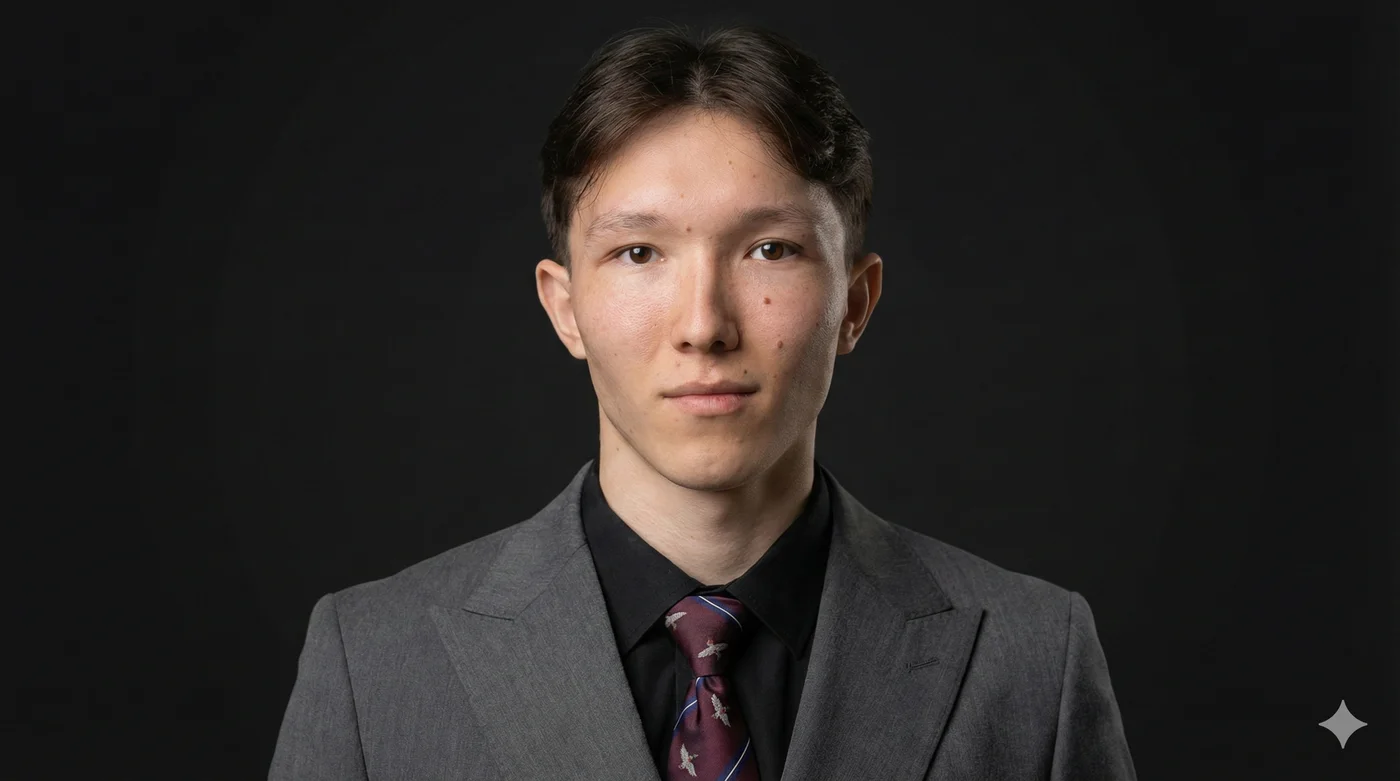
A few portraits from my personal archive. Another way to get to know the person behind the projects.
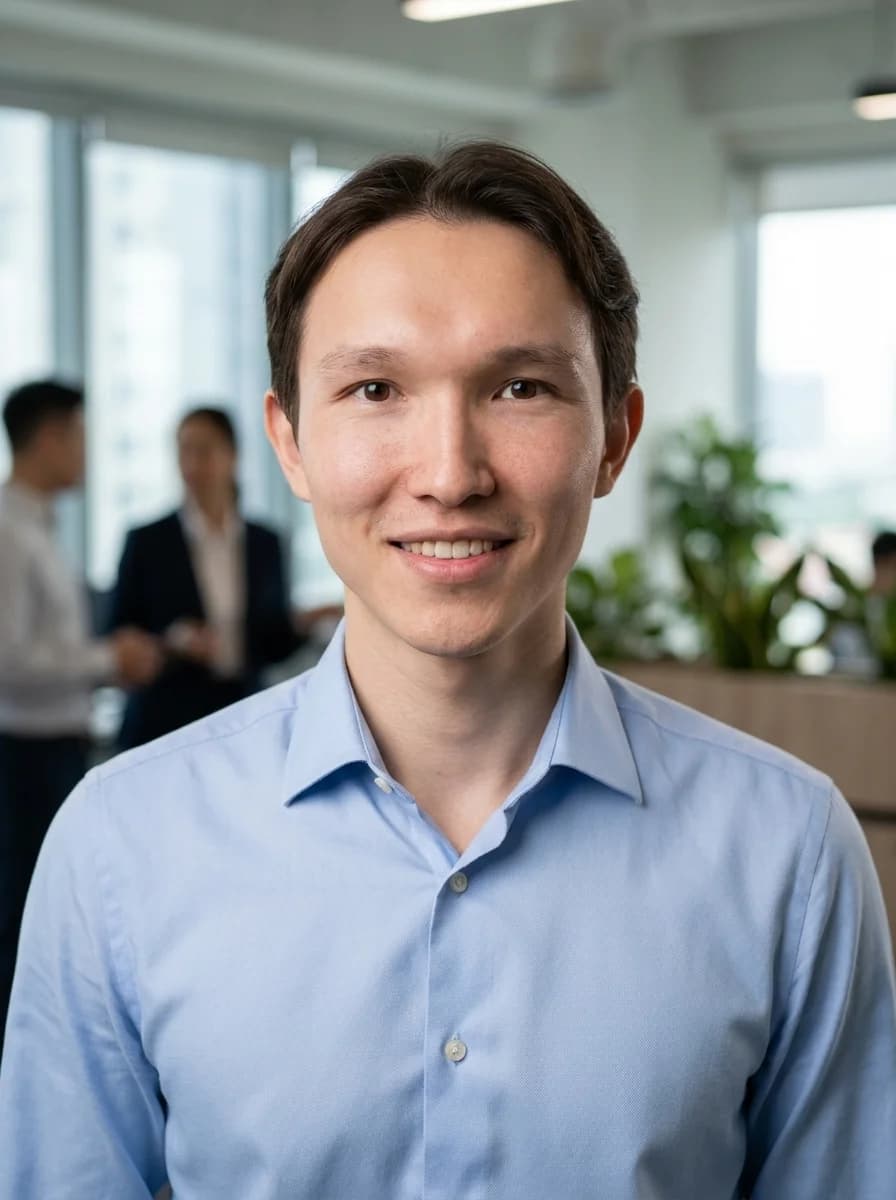
A little about me
Engineer, builder, always learning.
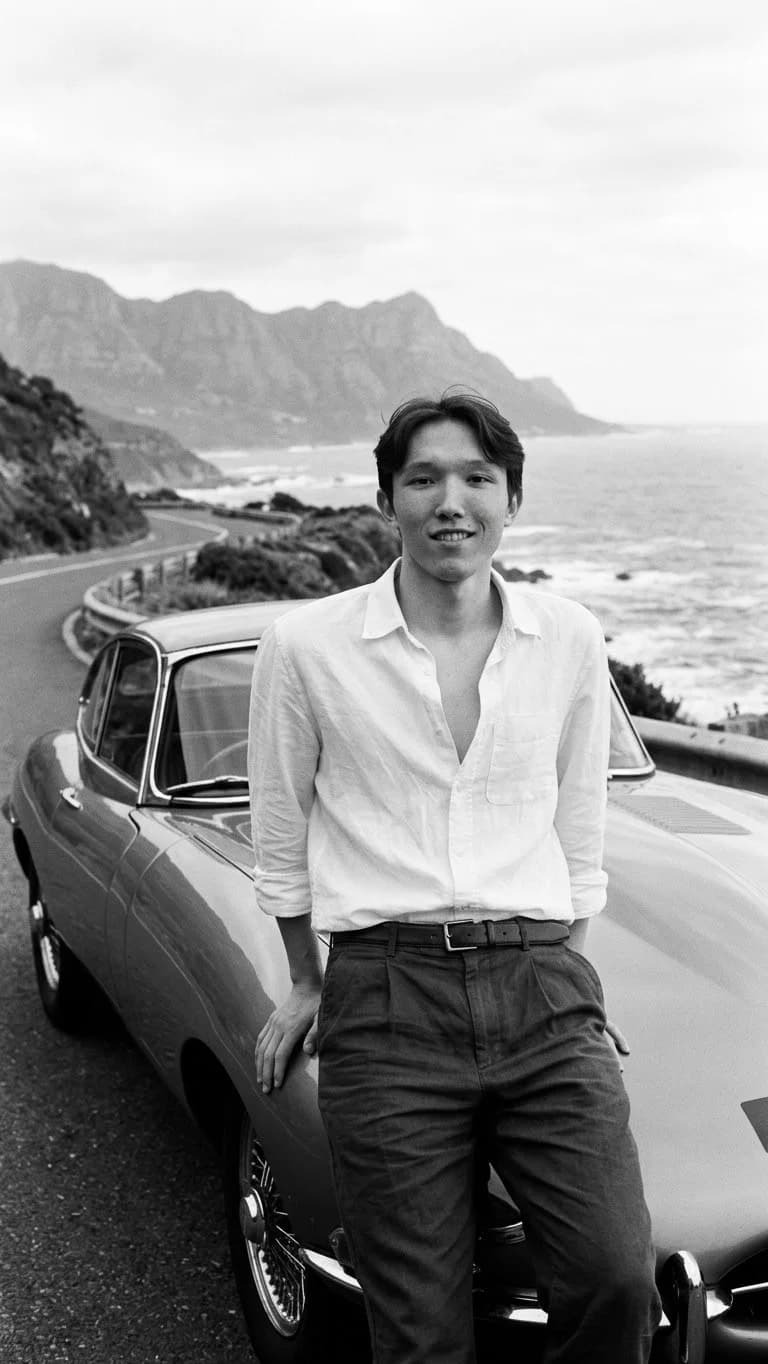
In black and white
A different frame of mind.
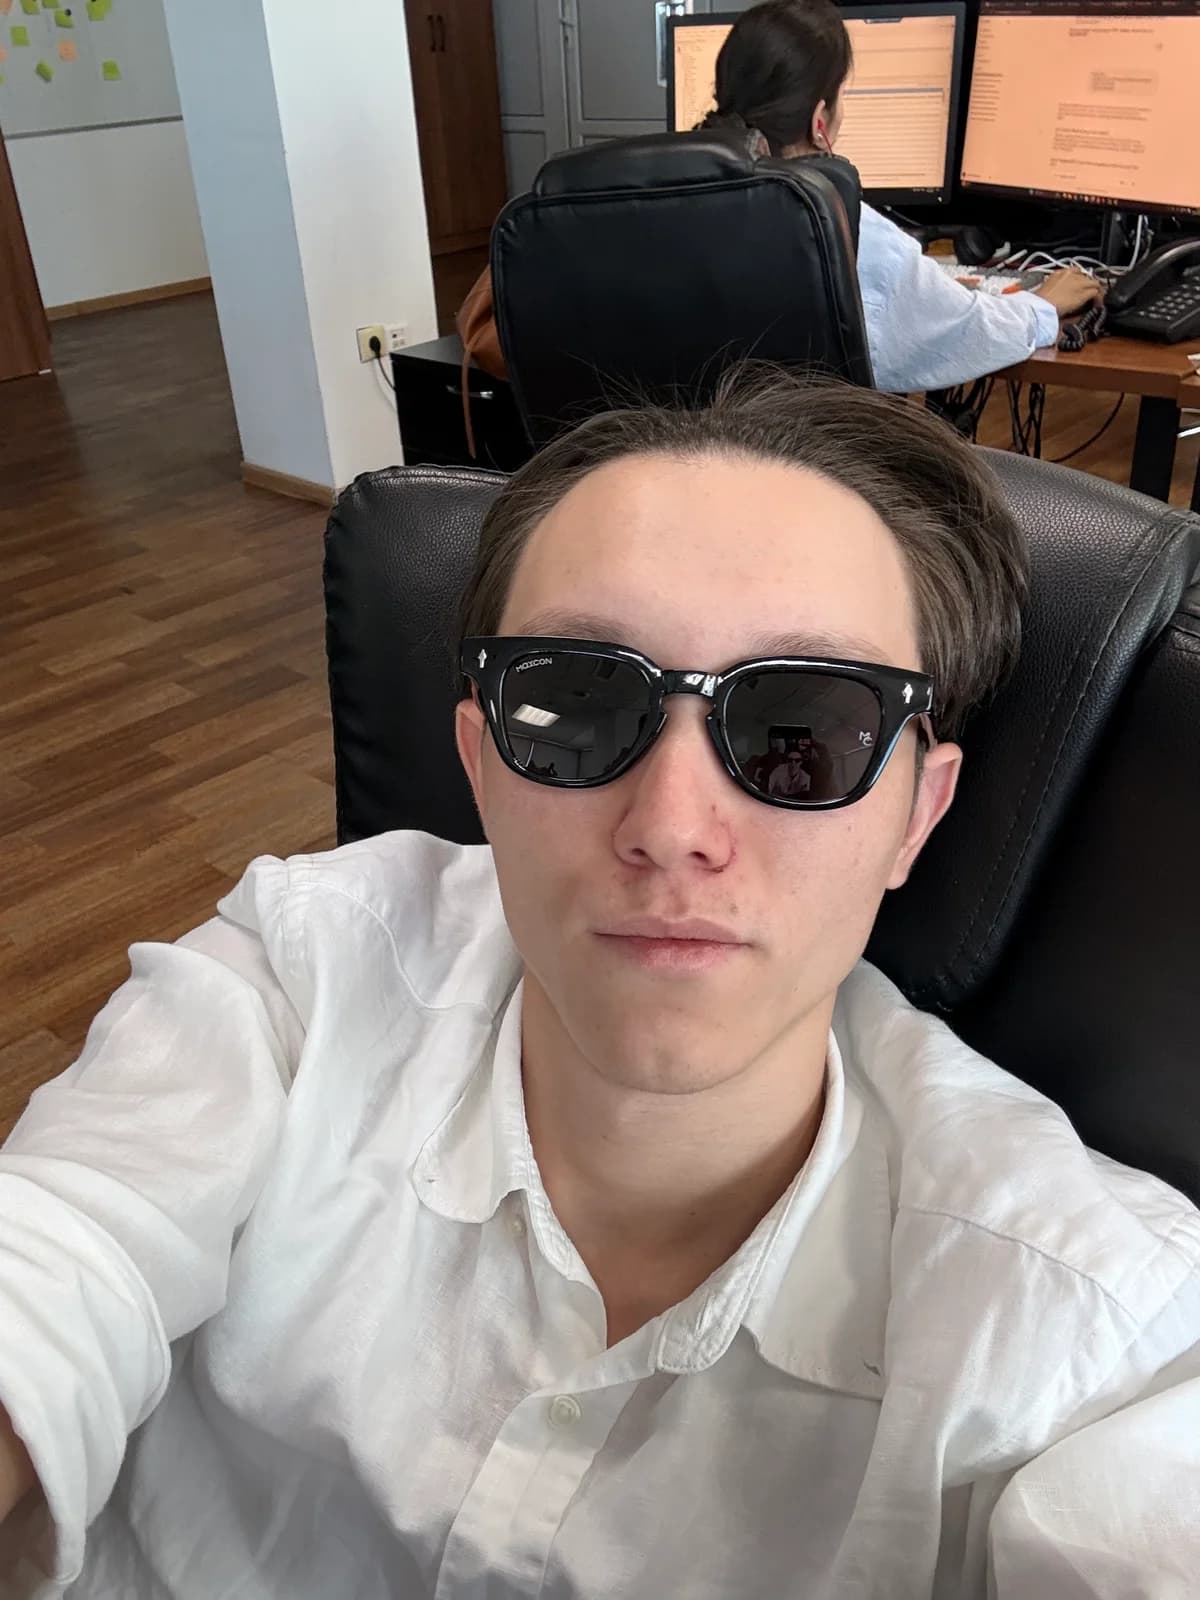
Between the projects
A candid moment from the everyday.
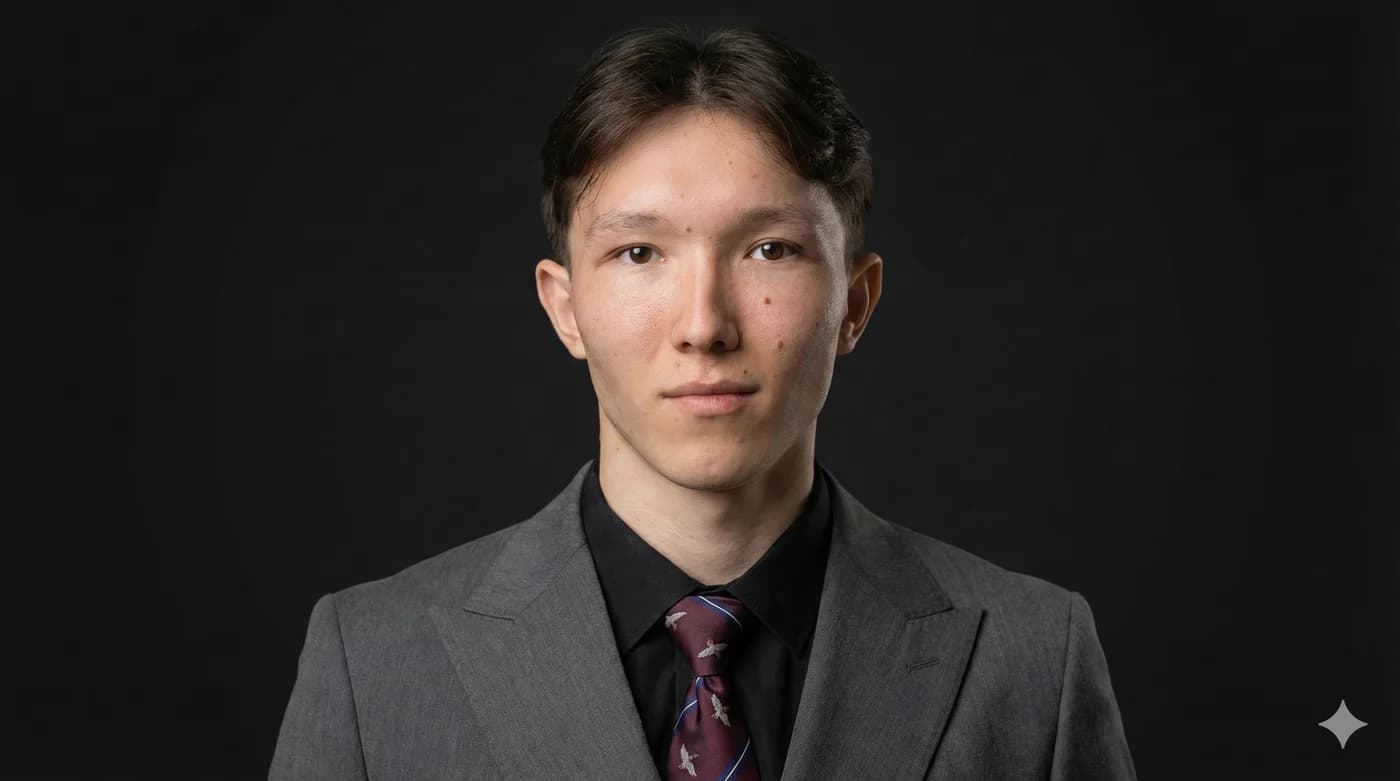
Another perspective
A portrait from my personal archive.